Paragraph 1:
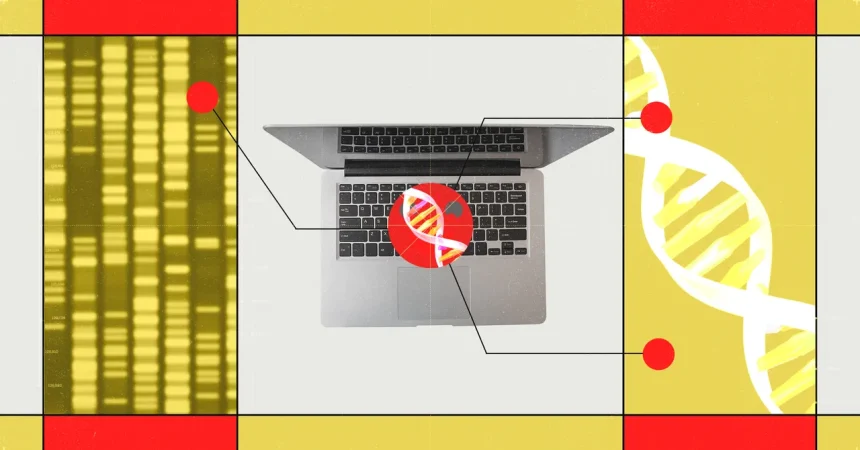
Imagine sitting at your kitchen table, opening a laptop, and being able to have a conversation with your own DNA. You could ask, “What does this tiny change in my gene actually do?” and receive a plain-English answer instead of a wall of scientific jargon. That is the kind of future Hugging Face is trying to make real. On Thursday, the company released an open model called Carbon-X, built in collaboration with researchers at Zhongguancun Academy in China and the University of Naples Federico II in Italy. It is designed to understand DNA the way large language models like ChatGPT understand English, but it’s also been trained on natural language, so you can ask questions about how genetic changes affect gene activity and health and get conversational responses. Lewis Tunstall, a senior research scientist at Hugging Face, described it as unlocking a new capability: being able to chat with DNA. For people who don’t have a PhD in genomics, this could be a game-changer. Instead of trying to parse raw sequence data or waiting for a specialist to interpret it, a researcher, a clinician, or even a curious patient could simply ask. The ambition is not to replace human expertise but to make DNA more accessible. It is meant to help researchers design new drugs and genetic therapies, and perhaps one day help patients better understand their own genetic information. The model is open, which means it can be downloaded and run on local hardware, and it’s small enough to run on a laptop. That matters for privacy, for speed, and for researchers who don’t have access to massive cloud computing clusters. In a field where progress has often been gated by expensive infrastructure, that’s a meaningful step.
Paragraph 2:
To understand why Carbon-X matters, it helps to know a little about Hugging Face itself. If you follow artificial intelligence, you’ve likely heard of it as something like the GitHub of AI models. Instead of hosting source code for software, it hosts thousands of pretrained models, datasets, and applications, many of them open-weight or open-source. Developers, researchers, and hobbyists use it to build AI tools without having to start from scratch. It’s a central hub in the AI ecosystem, and its influence is huge. In September, Nvidia agreed to acquire the company for nearly $13 billion, which shows how much big tech values the platform. Earlier this year, Hugging Face also found itself at the center of a security scare when OpenAI’s models were apparently used in a large-scale hack, but the company remains one of the most trusted names in the open AI community. Now, with Carbon-X, it’s stepping deeper into biology. The move makes sense when you consider DNA itself. DNA is often described as a biological code, and it really is code-like: instead of using 1s and 0s, it uses four chemical letters—A, C, G, and T—to store information. A single human genome contains about six billion of these letters, and even though scientists have fully sequenced it, we still don’t truly understand what most of it does. It’s like having the complete text of an enormous, ancient library in a language we’re only beginning to translate. That’s where modern AI comes in. Language models are essentially pattern detectors, and DNA is full of patterns. So why not train a model to read DNA the way it reads text? The challenge is that DNA isn’t exactly a natural language. It has its own grammar, its own structure, and its own way of encoding meaning, and it doesn’t map neatly to words. But with the right training, a model can begin to learn those patterns.
Paragraph 3:
Carbon-X is not the first AI model to take on DNA, but it is different from what came before. Last year, Google DeepMind released AlphaGenome, a powerful tool that can predict the effects of DNA sequences and genetic mutations. However, its outputs are numeric, and it requires substantial computational resources. Then there is Evo 2, developed by the Arc Institute, Nvidia, and academic partners, which speaks the language of DNA and can generate entire genomes from scratch. Both are impressive, but neither lets you have a back-and-forth conversation about what a mutation means. Carbon-X tries to combine both worlds: it understands DNA, and it understands human language. The team built it by starting with an existing language model and expanding its vocabulary so it could read DNA in groups of six letters, known as codons or tokens. They then continued training it on 300 billion chunks of data, called tokens, which mixed together DNA sequences, English text, and examples that link DNA to biological descriptions. The training data included DNA from mammals, including humans, as well as other vertebrates, invertebrates, plants, fungi, and protozoa. Notably, they deliberately left out viruses. The reason is safety: they didn’t want the model to be used to create dangerous biological weapons or to help someone engineer a pathogen. That’s a thoughtful precaution in an era where biological AI tools are increasingly powerful. But there’s a limitation built into the model as well: users won’t be able to upload a full human genome. Carbon-X was trained to handle DNA sequences of roughly 50,000 base pairs, so you can only query small sections of the genome at a time. That might sound restrictive, but for many real-world questions—like whether a single mutation in a particular gene is harmful—50,000 base pairs is often enough.
Paragraph 4:
So what would someone actually do with a DNA chatbot? The most immediate application is in research and drug development. When scientists are looking for a genetic cause of a disease, they often find many mutations, but not all mutations are equal. Some are harmless variants, while others disrupt gene function and lead to illness. Distinguishing between the two is crucial because if you develop a drug or a genetic therapy that targets the wrong mutation, it could be completely ineffective. Worse, it could cause unforeseen side effects by interfering with something that wasn’t broken in the first place. Carbon-X is designed to help with exactly that kind of question. You could present it with a specific DNA sequence, ask what a change at a certain position might do, and get a hypothesis in natural language. That doesn’t mean the answer is definitive—it’s a prediction, not an experiment—but it gives scientists a fast, intuitive way to prioritize which mutations deserve a closer look. It could also help in designing therapies by suggesting which parts of the genome to edit or target. Beyond the lab, there’s potential for patients. Many people are now getting their genomes or exomes sequenced, often through direct-to-consumer genetic tests or clinical diagnostics. The raw results are hard to interpret, and even the summaries can be confusing. A conversational tool like Carbon-X could, in theory, help someone understand a genetic report, ask follow-up questions, and get context. Of course, that comes with all the usual caveats about medical information and the need for professional guidance, but the basic idea is powerful. Being able to talk to your DNA, to ask it what it means, is the kind of capability that could democratize knowledge that was previously locked away in specialized institutions.
Paragraph 5:
One of the most thoughtful aspects of Carbon-X is its design around privacy and accessibility. When researchers work with genetic data, they often deal with identifiable and sensitive information. Uploading such data to a cloud-based AI service, even a secure one, can raise serious legal and ethical concerns. Patients’ genomic data is highly personal, and many people are wary of sharing it with tech companies. Tunstall and his team deliberately made Carbon-X small enough—about 14 billion parameters—to run locally on a user’s own hardware. It doesn’t require sending data to Hugging Face or any other company. That means a hospital, a university lab, or even an individual researcher could download the model and use it entirely on their own computers. The genetic data stays in their control, which is a significant advantage in a world where data breaches and misuse are constant worries. It also lowers the barrier to entry. A laptop is something most researchers have; a cluster of expensive GPUs with massive memory is not. By making the model open and reasonably lightweight, Hugging Face is doing more than just sharing a tool—it’s making sure that smaller labs and institutions in developing countries, which might not have the budgets of big tech companies, can also participate in cutting-edge genomic research. It is a reminder that powerful AI doesn’t always have to be centralized in a few giant servers. Sometimes the most useful tool is one that people can hold in their hands, or at least set up on their desk, with complete confidence that their most sensitive information isn’t leaving the room.
Paragraph 6:
There is, of course, a big caveat: Carbon-X has not yet been validated with actual wet lab experiments. The developers are honest about this. They don’t yet know how accurate its predictions are in real biological systems. A model can learn patterns from sequences and text, but biology is messy, and predictions need to be tested in cells, in animals, and ultimately in humans. A mutation predicted to be benign might turn out to be harmful, or vice versa. So while Carbon-X is a promising tool, it is not a clinical decision-maker. It’s more like a highly intelligent research assistant that can generate hypotheses and offer explanations. The hope is that with feedback from the scientific community, the model will improve and eventually become reliable enough for more serious applications. Still, there’s something remarkable about the moment. We have reached a point where an open, locally runnable model can converse with us about the language of life. It won’t replace scientists or doctors, but it could genuinely change how quickly they work and how easily they communicate with one another and with the public. It might also give everyday people a new sense of connection to their own biology. For many of us, DNA is something abstract, a double helix we see in textbooks. But it’s also the reason our eyes are a certain color, the reason we might be at risk for certain diseases, and the reason we are who we are. Being able to ask questions of that code, in plain language, is a kind of democratization. We’re not all geneticists, but we all have genomes. Tools like Carbon-X bring us a little closer to understanding them, not through dense tables and mathematical scores, but through conversation. That’s a small, humanizing step in a field that can often feel cold and technical. And it’s only the beginning. As models get better, as they’re tested in labs and refined with real data, the ability to chat with DNA may become as ordinary as asking a digital assistant for the weather. The mystery of the genome won’t vanish overnight, but at least now we have a new way to ask it questions. And that’s a genuinely exciting thought.